Payment systems are among the most business-critical components of any digital platform. A small spike in latency, an unexpected drop in authorization rates, or a silent outage in a single provider can translate into immediate revenue loss. This guide explains how to design effective monitoring and alerting strategies for production payment systems, with a focus on reliability, performance, and fast incident response.
What makes monitoring production payment systems different from other systems?
Production payment systems operate under stricter requirements than most application components. They handle money movement, sensitive data, and real-time user interactions, often across multiple external providers.
Unlike internal services, payment flows depend on acquirers, gateways, fraud tools, networks, and banks. This means failures are not always binary outages; they often appear as gradual performance degradation, regional issues, or provider-specific anomalies that traditional uptime monitoring cannot detect.
Which metrics are critical to monitor in payment systems?
Effective payment monitoring starts with the right metrics. These should reflect business impact, not just infrastructure health.
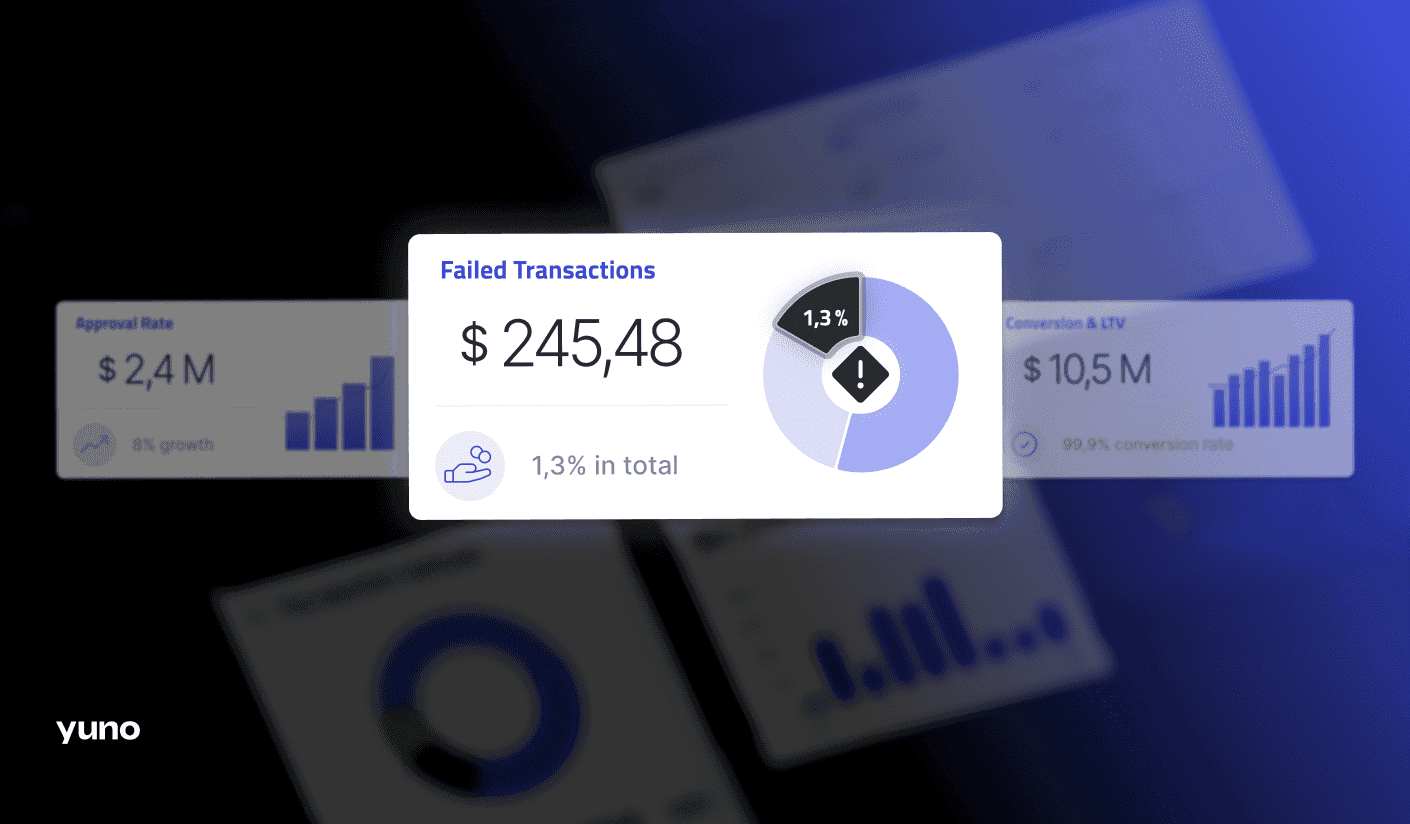
Key categories include authorization metrics (approval rate, soft vs. hard declines), latency metrics (time to authorization, provider response times), error metrics (timeouts, malformed responses, retry failures), and volume metrics (transactions per second, regional traffic distribution).
Monitoring approval rate trends over time is especially important, as small drops often indicate upstream issues long before a full outage occurs.
How should alerting thresholds be defined for payment metrics?
Static thresholds are rarely sufficient for payment systems. Normal performance varies by region, payment method, issuer, and time of day.
Best practices include using dynamic or baseline-based thresholds that trigger alerts when metrics deviate from expected behavior rather than fixed values. For example, a sudden 3–5% drop in approval rates for a specific provider or country may warrant investigation even if absolute values still look acceptable.
Alert severity should be tied to business impact, distinguishing between informational alerts, degradation warnings, and critical incidents.
Why is provider-level monitoring essential in multi-provider setups?
Modern payment stacks often rely on multiple gateways, acquirers, and fraud services. Monitoring only the aggregate system can hide provider-specific failures.
Provider-level observability allows teams to identify issues such as increased latency from a single gateway, higher decline rates from a specific acquirer, or intermittent errors in a fraud tool. This visibility enables faster mitigation actions, such as rerouting traffic or adjusting retry logic.
This is particularly relevant for teams using payment orchestration, where traffic can be dynamically distributed across providers.
How can real-time alerts reduce revenue loss during incidents?
Speed is critical when payment issues occur. The longer an issue goes undetected, the more transactions fail silently.
Real-time alerts based on transaction performance allow teams to react within seconds instead of minutes. For example, immediate alerts on abnormal latency or approval rate drops can trigger automated responses or manual intervention before customers notice widespread failures.
Many teams complement alerts with automated workflows that pause traffic to affected providers while the issue is investigated.
What role does anomaly detection play in payment monitoring?
Not all payment issues follow predictable patterns. Anomaly detection helps identify unexpected behavior that rule-based alerts may miss.
Examples include unusual spikes in retries, sudden changes in decline reasons, or abnormal traffic shifts between regions. Anomaly-based monitoring is especially valuable in high-volume environments where manual analysis is impractical.
Advanced monitoring setups continuously learn from historical data to improve detection accuracy and reduce false positives.
How should monitoring dashboards be structured for payments teams?
Dashboards should provide a clear, real-time view of payment health at both high and granular levels.
Effective dashboards typically include an executive overview (global approval rate, error rate, volume), operational views (provider and region breakdowns), and diagnostic views (error codes, latency percentiles, retry behavior).
Dashboards should support fast drill-down, allowing teams to move from a high-level alert to root cause analysis within seconds.
How do monitoring and alerting support incident response and recovery?
Monitoring is only valuable if it enables action. Alerting should integrate with incident management processes, including on-call rotations, escalation paths, and post-incident reviews.
Clear alerts help teams quickly identify whether an issue is internal or external, isolated or systemic. This reduces mean time to detection (MTTD) and mean time to resolution (MTTR), two critical metrics for payment reliability.
Teams that regularly review alerts and incidents can continuously refine thresholds and improve system resilience.
How does automated payment monitoring improve long-term performance?
Beyond incident response, monitoring data provides insights into long-term optimization opportunities. Trends in approval rates, latency, and provider performance can inform routing strategies, provider negotiations, and fraud configuration.
For a deeper discussion on how automated monitoring can help detect issues earlier and reduce revenue impact, see the webinar replay "Recover Revenue with Automated Payment Monitoring", which covers practical approaches to payment monitoring and alerting.
How do payment orchestration platforms support monitoring and alerting?
Payment orchestration platforms centralize transaction data across providers, making monitoring significantly more effective. Instead of stitching together logs and metrics from multiple systems, teams gain a unified view of payment performance.
This centralized approach enables real-time alerts, faster anomaly detection, and coordinated responses such as rerouting traffic or adjusting payment flows without engineering intervention.